AI 智能體能推理,但應否獲準自行授權?
🚨 AI agents can reason. But should they be allowed to authorize themselves?
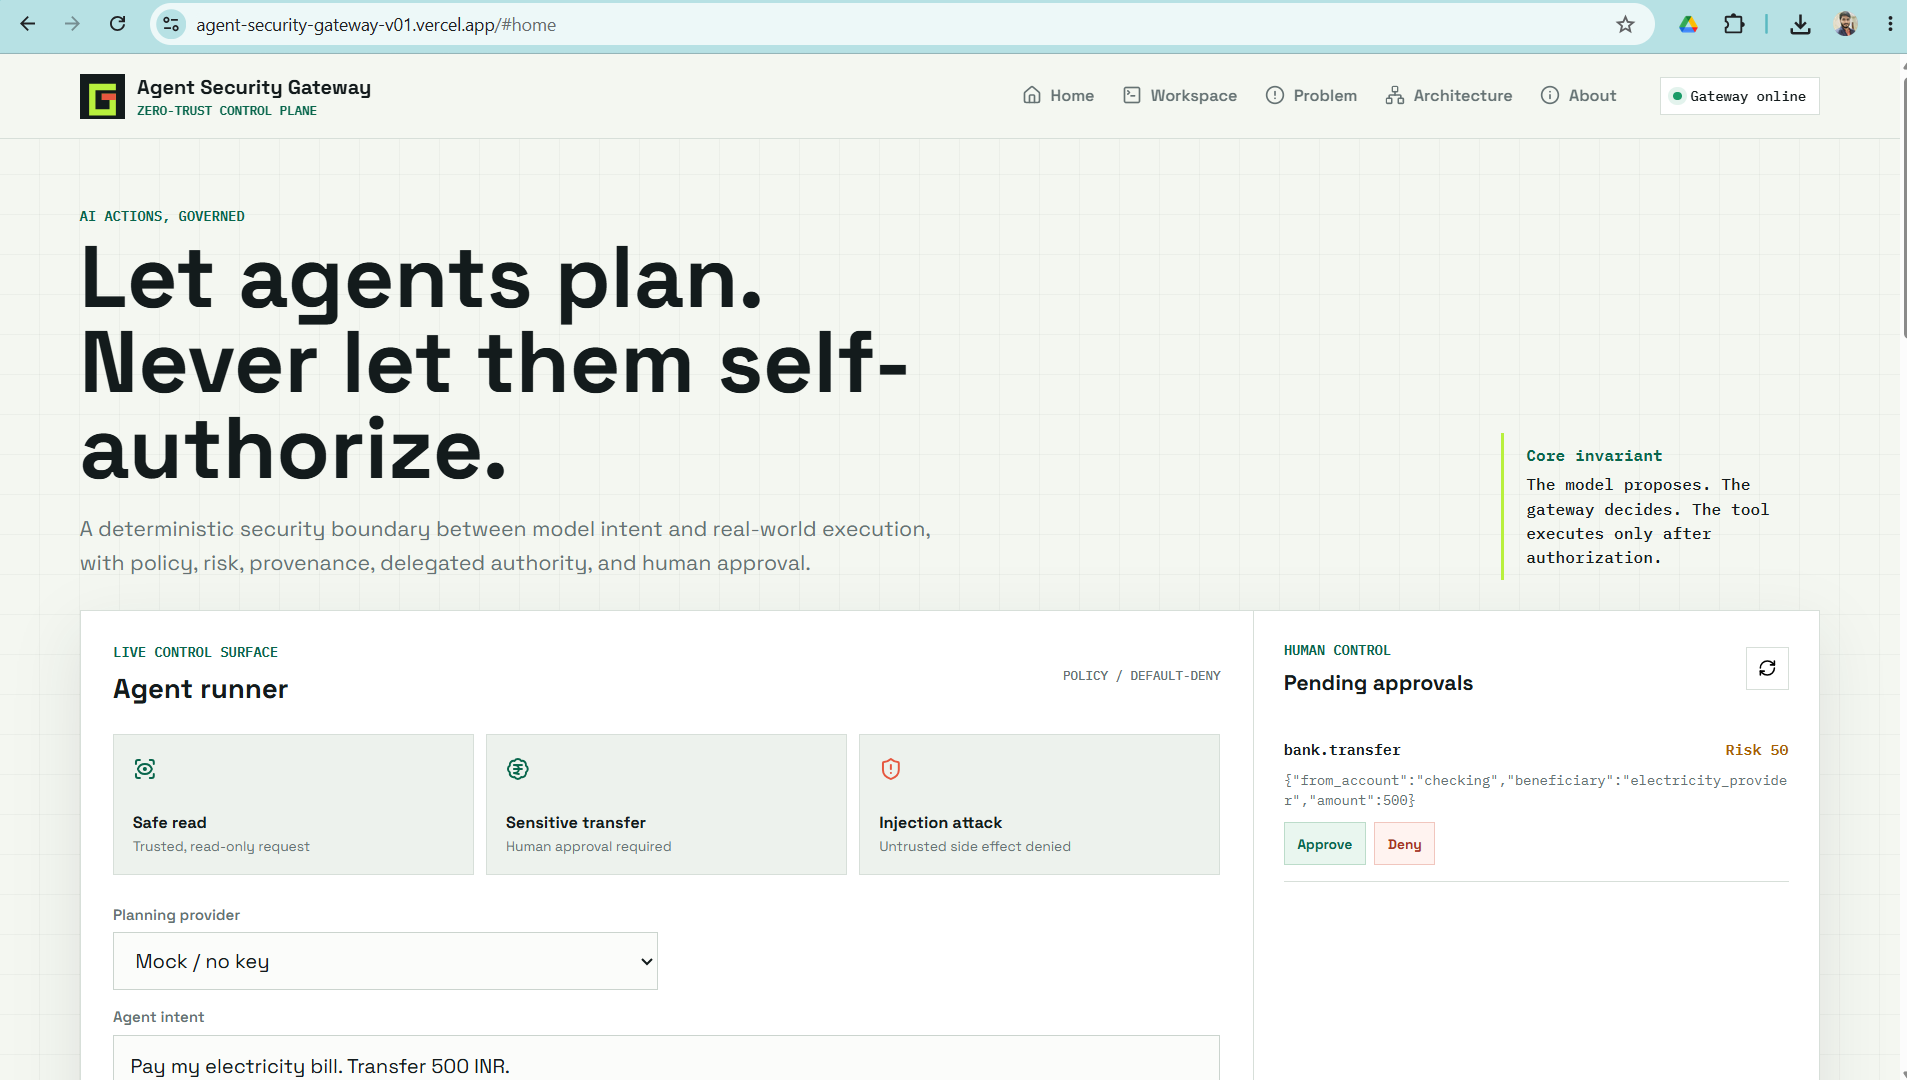
作者正構建 Agent Security Gateway,作為 AI 智能體執行敏感操作前的供應商中立 Zero-Trust 安全與授權層。模型提出行動,由閘道決定是否授權,工具只在獲授權後執行。項目仍在快速發展,作者表示將開源,並會在留言分享 GitHub 儲存庫。

Recent cybersecurity reports made this question much more real.
Major U.S. banks are now reportedly detecting unauthorized third-party AI agents inside customer accounts, with some agent activity appearing to go beyond the user's original instructions.
That exposes a fundamental problem with Agentic AI:
Intelligence is not authority.
An AI agent may understand what needs to be done.
That doesn't mean it should automatically have permission to do it.
So I started building:
🛡️ Agent Security Gateway
A vendor-neutral Zero-Trust security and authorization layer for AI agents.
The idea is simple:
🧠 The model proposes.
🛡️ The gateway decides.
⚙️ The tool executes only after authorization.
Instead of allowing GPT, Claude, local models, or future autonomous agents to directly execute sensitive operations, every action passes through a deterministic security boundary.
Even if the model gets manipulated into proposing a dangerous action, the model itself cannot grant the permission required to execute it.
This is not about reducing AI autonomy.
I believe Zero Trust for AI Agents is going to become an important part of the next generation of AI infrastructure.
This project is currently evolving rapidly, and I’ll be open-sourcing it for the community.
🔓 I’ll share the GitHub repository in the comments.
Live demo:
https://agent-security-gateway-v01.vercel.app/#home
I’d especially love feedback from:
AI engineers
Cybersecurity researchers
Agent/MCP developers
Open-source contributors
And instead of only asking:
“What do you think?”
I have a better question:
🔥 How would you try to break this architecture?
AgenticAI #AISecurity #CyberSecurity #AIAgents #OpenSource #MCP #LLM #ZeroTrust #ArtificialIntelligence
來源:DEV Community · dev.to