如何利用 Amazon SageMaker HyperPod Data Capture 建立模型改進飛輪
Build a model improvement flywheel with Amazon SageMaker HyperPod Data Capture
Amazon SageMaker HyperPod Data Capture 提供三個獨立層級的擷取方式,讓團隊把推理數據記錄至 Amazon S3,供分析和訓練使用。
文章以合成資料展示從生產推理記錄、Athena 分析到 SQL 標註與微調的完整流程,並比較留出測試的前後結果。
部署在 Amazon SageMaker HyperPod 上的基礎模型會遇到預先整理的數據集未涵蓋的輸入:特定領域的術語、意料之外的格式、新產品,以及不斷變化的用戶行為。如果沒有生產環境推理數據的記錄,團隊就無法偵測數據漂移、找出故障模式,或利用實際互動改善模型。
Amazon SageMaker HyperPod 現已提供 Data Capture,這項內置功能可將即時推理的輸入和輸出記錄到 Amazon Simple Storage Service (Amazon S3) 的三個獨立層級,同時將延遲影響降至最低,並且不會影響模型的可用性。
本文會以單一 SageMaker HyperPod 叢集為例,完整介紹整個流程。家電支援路由器會擷取其生產環境流量;Amazon Athena 查詢會揭示對新產品的盲點;SQL 政策會為擷取的記錄加上標籤;再以這些數據進行微調,讓路由器學習新產品。我們會在模型部署前不可能存在的數據上,量度微調前後的準確度。推理運算子會在一個節點上提供模型服務,而訓練運算子則在另一個節點上執行微調。
本文示範會使用合成數據。相關指令碼、資訊清單、SQL、合成數據集及預期輸出,均可在隨附的 GitHub 儲存庫取得。
三層式 Data Capture 架構
HyperPod Data Capture 提供三個獨立層級,分別位於請求路徑的不同位置。你可以在同一個 dataCapture 區塊中啟用任意組合。
| 第 1 層:SageMaker 端點 | 第 2 層:負載平衡器 | 第 3 層:模型 Pod | |
| 擷取內容 | 完整請求/回應承載資料 | Application Load Balancer (ALB) 存取日誌欄位:請求行、狀態碼、計時資料、用戶端 IP、用戶代理程式 | 完整請求/回應承載資料及事件中繼資料 |
| 管理方式 | SageMaker 原生數據擷取 | ALB 存取日誌 | HyperPod 推理運算子(NGINX + OTel 收集器 + S3 上載器 sidecar) |
| 最適用於 | 合規、Model Monitor、稽核 | 以低成本監察流量和錯誤率 | 偵錯、分析、收集訓練數據 |
| 設定 | sagemakerEndpoint: — 抽樣比例、輸入/輸出、AWS KMS |
loadBalancer: { enabled: true } |
modelPod: — 抽樣比例、輸入/輸出、緩衝區、承載資料大小上限、AWS KMS、內容類型 |
第 1 層和第 3 層都會儲存完整承載資料,因此同時啟用兩者會將每筆記錄儲存兩次。合規和 Model Monitor 用途請選用第 1 層;只需要流量中繼資料時請選用第 2 層;打算使用承載資料時則請選用第 3 層。本文只使用第 3 層。由於第 3 層會記錄完整承載資料,其中可能包括姓名、地址和訂單編號,因此在將這些資料用作訓練數據前,必須先加以保護。請使用抽樣、AWS Key Management Service (AWS KMS) 加密(kmsKeyId)、S3 生命週期規則,以及個人識別資料 (PII) 遮蔽(例如使用 Amazon Comprehend)。
先決條件
- 由 Amazon Elastic Kubernetes Service (Amazon EKS) 編排的 SageMaker HyperPod 叢集,並已安裝推理運算子(設定 HyperPod 叢集以部署模型)及訓練運算子 EKS 附加元件
amazon-sagemaker-hyperpod-training-operator(安裝訓練運算子)。 - 兩個可用的 NVIDIA GPU,一個用於提供服務,另一個用於訓練。我們使用
ml.g6e.8xlarge提供服務,並使用ml.g6e.xlarge進行訓練(各配備一張 48 GB NVIDIA L40S)。服務 Pod 會在端點運作期間一直佔用其 GPU,因此如果只有一個 GPU,訓練 Pod 便會維持Pending狀態。 - 已為叢集設定的
kubectl。 - 位於相同區域的 S3 儲存貯體。
確認兩個 Operator 均已安裝。命令會傳回兩列:
kubectl get crd | grep -E 'inferenceendpointconfigs|hyperpodpytorchjobs'
hyperpodpytorchjobs.sagemaker.amazonaws.com                         2026-09-21T10:57:14Z
inferenceendpointconfigs.inference.sagemaker.aws.amazon.com         2026-08-06T11:58:53Z
方案概覽
下圖展示在單一 SageMaker HyperPod 叢集上逐步完成的五個步驟:將每個請求和回應擷取至 Amazon S3,使用 Athena 分析擷取資料,以 SQL 政策為資料加上標籤,透過訓練 Operator 在第二張 GPU 上進行微調,然後在仍啟用擷取功能的情況下並排重新部署。
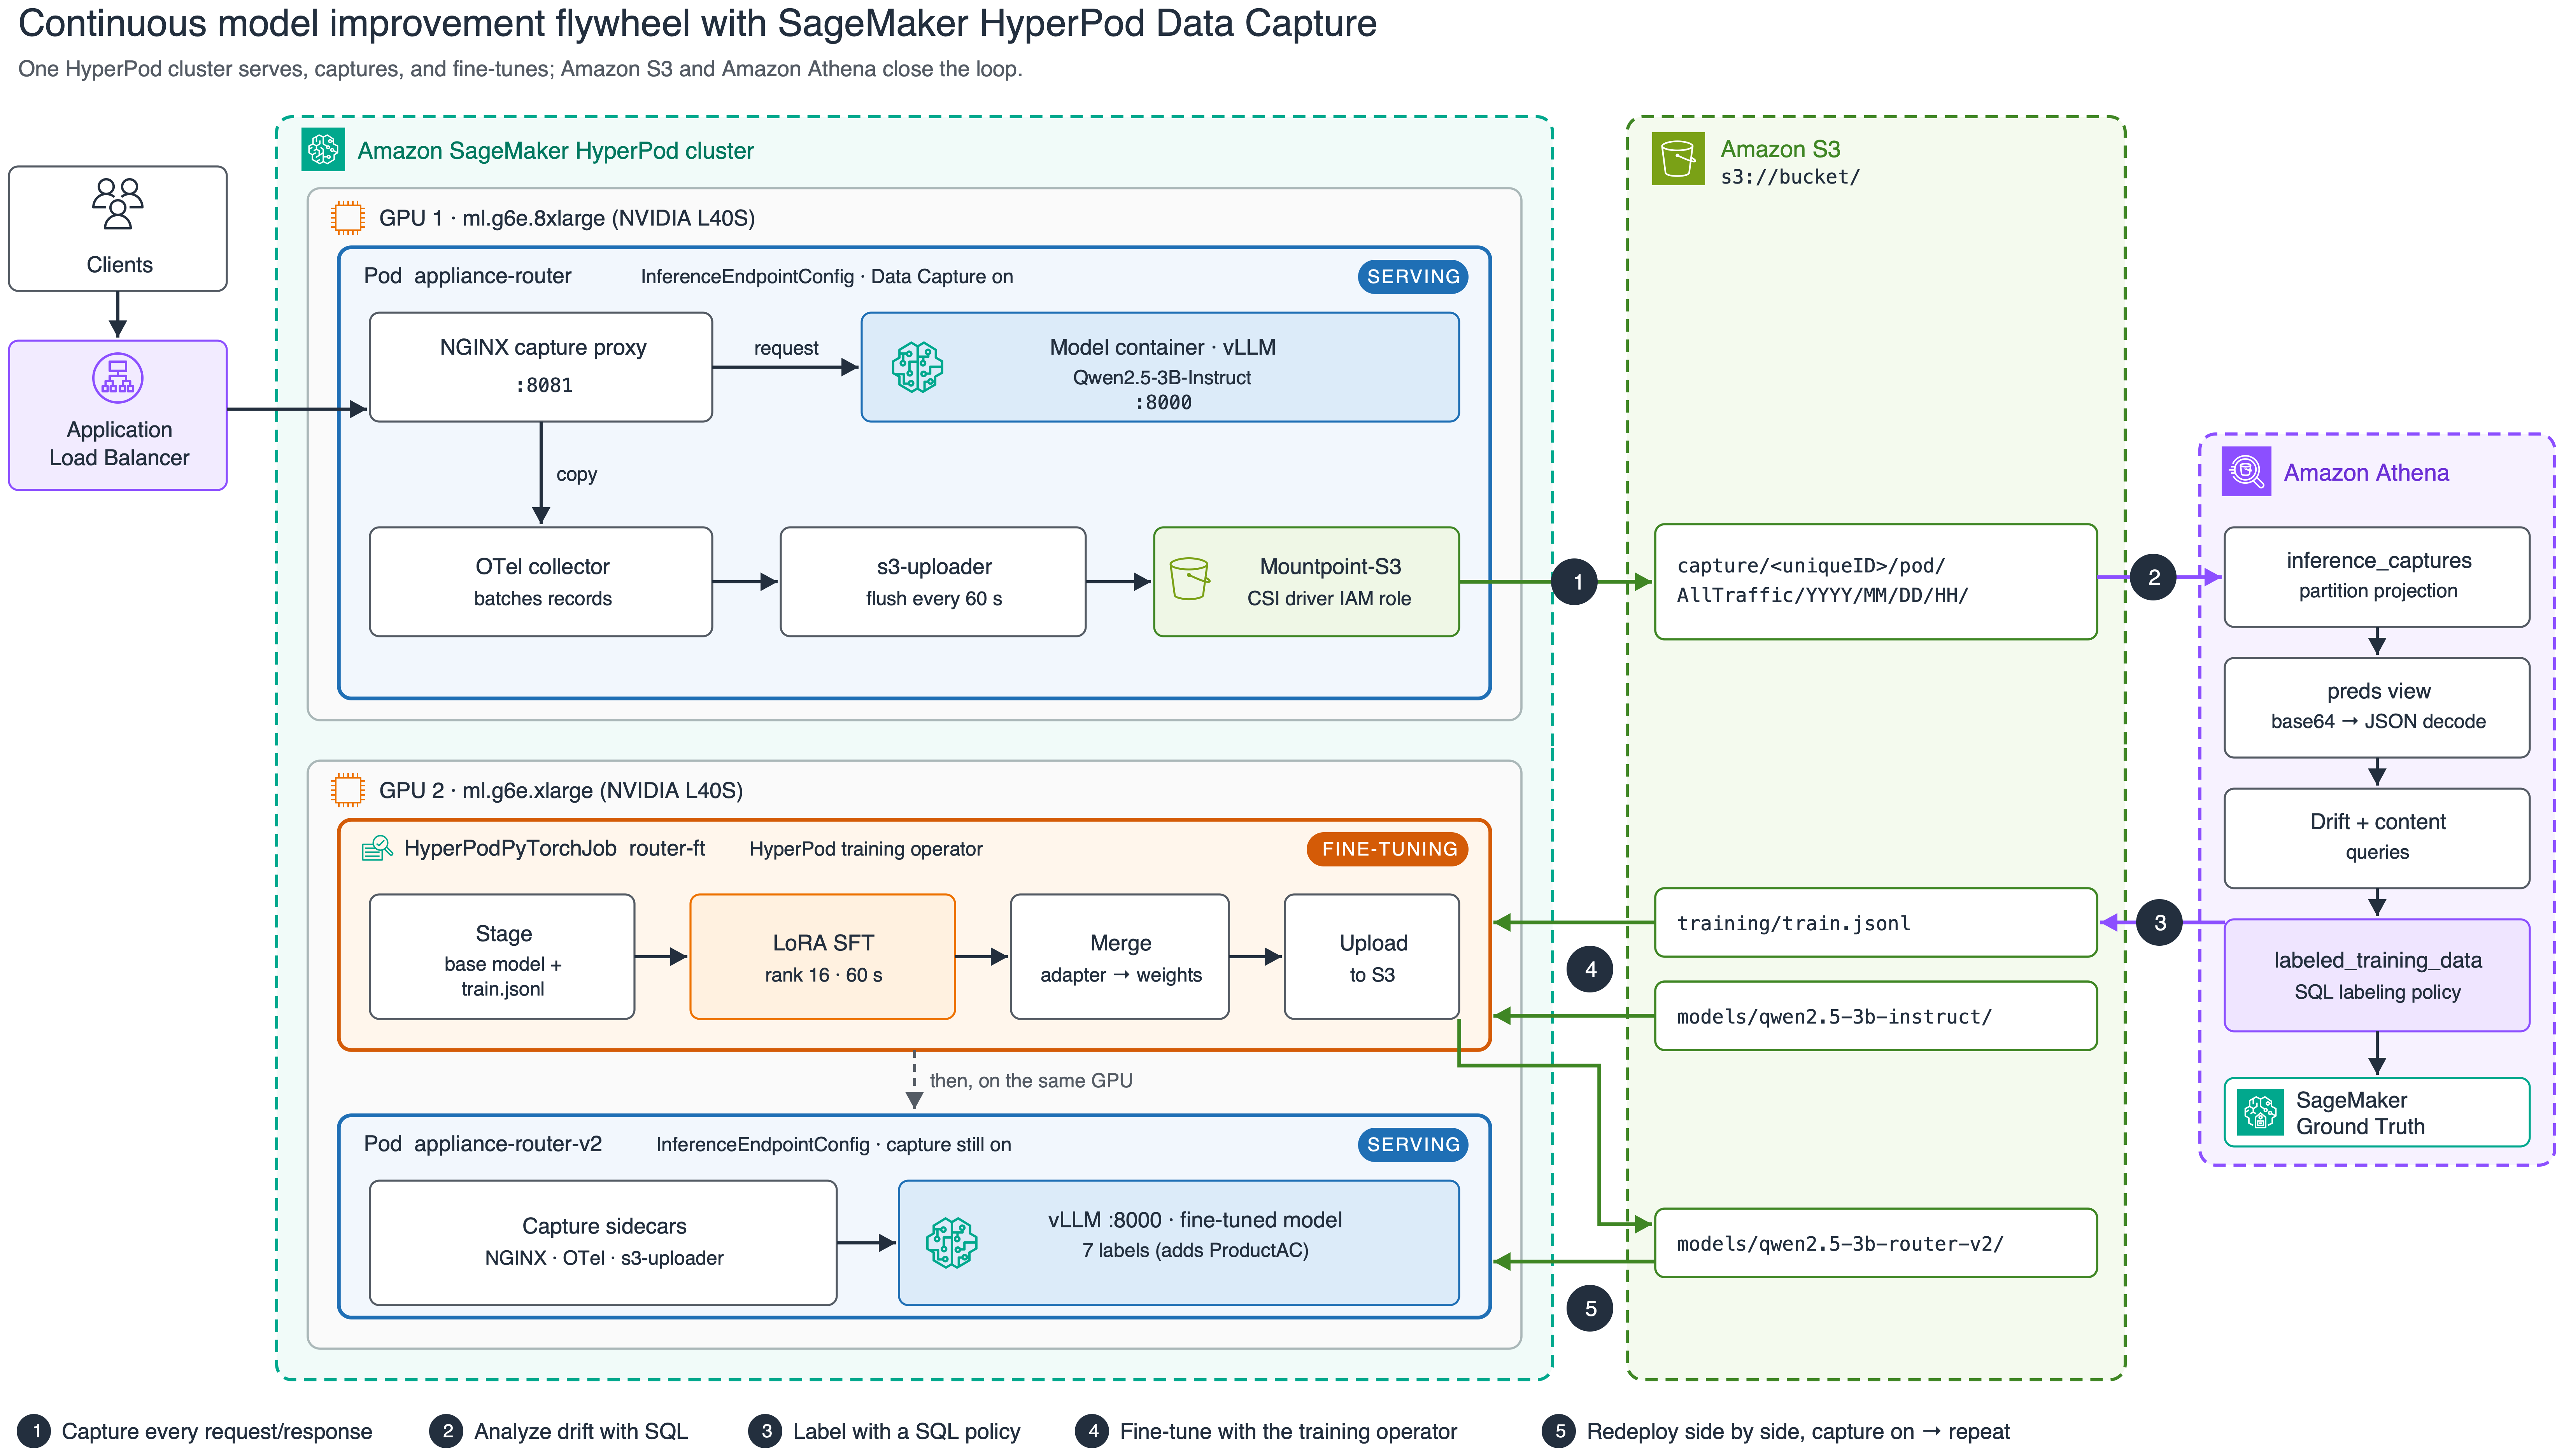
圖 1:單一 SageMaker HyperPod 叢集上的五步飛輪,從資料擷取、Athena 分析、標註、微調到重新部署
Inference Operator 會在模型 Pod 中加入三個 sidecar 容器。每個經過 NGINX Proxy 的請求都會複製到 OpenTelemetry 收集器,經批次處理後,透過 Mountpoint-S3 磁碟區寫入 S3。Athena 會直接讀取這些檔案。訓練 Operator 會在第二張 GPU 上以 HyperPodPyTorchJob 執行微調,而新模型會由另一個同樣啟用擷取功能的端點提供服務。
步驟 0:設定變數
後續每個步驟都會讀取這些變數。請編輯第一個區塊,然後貼上整段內容:
# --- edit these ---
export EKS_CLUSTER_NAME="my-hyperpod-eks"
export AWS_REGION="us-east-1"
export BUCKET="amzn-s3-demo-bucket"
export SERVE_INSTANCE_TYPE="ml.g6e.8xlarge"     # node type for the first endpoint
export TRAIN_INSTANCE_TYPE="ml.g6e.xlarge"      # node type for the fine-tuning job
# --- leave as-is ---
export AWS_DEFAULT_REGION="$AWS_REGION"
export ENDPOINT_NAME="appliance-router"
export MODEL_LOCATION="models/qwen2.5-3b-instruct"
export MODEL_V2_LOCATION="models/qwen2.5-3b-router-v2"
export TRAIN_SA="flywheel"                     # service account with S3 access via EKS Pod Identity
aws eks update-kubeconfig --name "$EKS_CLUSTER_NAME" --region "$AWS_REGION"
render() { python3 -c 'import os,sys; sys.stdout.write(os.path.expandvars(sys.stdin.read()))'; }
步驟 1:將基礎模型暫存至 S3
我們使用 Qwen2.5-3B-Instruct,因為它體積夠小,可在約一分鐘內完成微調,而且適用於單張 L40S GPU。
pip install -q huggingface_hub
python3 -c "from huggingface_hub import snapshot_download; \
  snapshot_download('Qwen/Qwen2.5-3B-Instruct', local_dir='qwen2.5-3b-instruct')"
aws s3 sync qwen2.5-3b-instruct "s3://${BUCKET}/${MODEL_LOCATION}/" --exclude ".cache/*"
步驟 2:IAM 權限
有四個身分需要存取權限。如需政策陳述式,請參閲 HyperPod 推理資料擷取。
- Mountpoint-S3 CSI 驅動程式角色。Tier 3 資料擷取會透過 Mountpoint-S3 磁碟區寫入,而驅動程式會以其專屬的服務帳戶 IAM 角色 (IRSA) 進行驗證,而非使用 Pod 的服務帳戶。它需要在您的擷取儲存貯體上具備
s3:PutObject、s3:AbortMultipartUpload和s3:DeleteObject權限,以及kms:Decrypt、kms:GenerateDataKey和kms:DescribeKey權限(如有設定kmsKeyId)。如果缺少這些權限,端點仍會保持正常,請求亦會成功,但不會出現任何擷取記錄。請參閲 Mountpoint for Amazon S3 CSI driver。 - Inference Operator 執行角色。它需要在您的擷取儲存貯體上具備
s3:PutObject權限,以及kms:Decrypt和kms:GenerateDataKey權限(如有設定kmsKeyId)。擷取檔案本身是透過 CSI 驅動程式角色寫入,因此如果沒有擷取記錄,請先檢查該角色。 - 訓練 Pod 的服務帳戶(
$TRAIN_SA)。透過 EKS Pod Identity 取得基礎模型和訓練資料的讀取權限,以及合併模型的寫入權限。 - Athena。擷取前綴的讀取權限,以及查詢結果的儲存位置。
啟用資料擷取
接下來三個步驟會部署已啟用 Tier 3 資料擷取的路由器、檢查 Pod 是否正在執行擷取 sidecar 容器,並確認記錄已寫入 Amazon S3。
步驟 3:部署已啟用 Tier 3 資料擷取的模型
這項功能只涉及 dataCapture.modelPod.enabled: true 區塊。其他部分都是一般的 vLLM 部署。
cat > endpoint.yaml <<'YAML'
apiVersion: inference.sagemaker.aws.amazon.com/v1
kind: InferenceEndpointConfig
metadata:
  name: ${ENDPOINT_NAME}
  namespace: default
spec:
  replicas: 1
  modelName: ${ENDPOINT_NAME}
  endpointName: ${ENDPOINT_NAME}
  instanceType: ${SERVE_INSTANCE_TYPE}
  invocationEndpoint: v1/chat/completions
  modelSourceConfig:
    modelSourceType: s3
    modelLocation: ${MODEL_LOCATION}
    s3Storage:
      bucketName: ${BUCKET}
      region: ${AWS_REGION}

  # >>> This is all you need to turn on Tier 3 data capture <<<
  dataCapture:
    s3Uri: "s3://${BUCKET}/capture/"
    modelPod:
      enabled: true
      initialSamplingPercentage: 100
      bufferConfig:
        batchSize: 50
        flushIntervalSeconds: 60
      payloadConfig:
        maxPayloadSizeKB: 1024

  worker:
    image: vllm/vllm-openai:v0.10.0
    modelInvocationPort:
      containerPort: 8000
      name: http
    modelVolumeMount:
      mountPath: /opt/ml/model
      name: model-weights
    args: ["--model", "/opt/ml/model", "--served-model-name", "${ENDPOINT_NAME}",
           "--port", "8000", "--max-model-len", "2048", "--gpu-memory-utilization", "0.90"]
    resources:
      requests: { cpu: "2", memory: 16Gi, nvidia.com/gpu: 1 }
      limits:   { nvidia.com/gpu: 1 }
YAML
render < endpoint.yaml | kubectl apply -f -
上述 modelPod 區塊會設定 100% 取樣,並同時擷取輸入和輸出,這些都是預設值。如要調整設定,可在 modelPod 下加入以下任何選用欄位:
modelPod:
  enabled: true
  initialSamplingPercentage: 50          # capture 50% of requests (default 100)
  bufferConfig:
    batchSize: 100                       # records buffered per upload batch (default 10)
    flushIntervalSeconds: 60             # max seconds before a flush (default 60)
  payloadConfig:
    maxPayloadSizeKB: 1024               # truncate payloads larger than this (default: no limit)
  kmsKeyId: "arn:aws:kms:...:key/..."    # encrypt captures at rest
步驟 4:等待 Pod
已啟用資料擷取的 Pod 會執行四個容器:模型、sidecar-reverse-proxy(NGINX)、otel-collector 和 s3-uploader。模型容器和 Pod 的 app 標籤都以 modelName 命名。
kubectl get pods -l app=$ENDPOINT_NAME -o custom-columns=\
'NAME:.metadata.name,READY:.status.containerStatuses[*].ready,CONTAINERS:.spec.containers[*].name,NODE:.spec.nodeName'
NAME                            READY                 CONTAINERS                                                              NODE
appliance-router-849f466476-4f5v8 true,true,true,true appliance-router,s3-uploader,sidecar-reverse-proxy,otel-collector hyperpod-i-0f3fe2684afd6a583在我們的執行過程中,kubectl apply 後約五分鐘 Pod 便準備就緒,大部分時間都用於下載權重。
步驟 5:傳送請求並確認擷取資料已寫入 S3
透過 8081 連接埠上的擷取 Proxy 傳送推理請求,然後等待資料寫入間隔過後,列出擷取前綴。模型本身會在 8000 連接埠監聽。傳送至該連接埠的請求會略過 Proxy,因此不會被擷取。
POD=$(kubectl get pod -l app=$ENDPOINT_NAME -o jsonpath='{.items[0].metadata.name}')
kubectl port-forward "pod/$POD" 18081:8081 >/dev/null 2>&1 &
sleep 5

curl -s http://localhost:18081/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{"model":"'"$ENDPOINT_NAME"'","messages":[{"role":"user","content":"my fridge is not cooling"}],"max_tokens":24}'

echo "Waiting for the capture buffer to flush..."; sleep 75
aws s3 ls "s3://${BUCKET}/capture/" --recursive | grep '\.jsonl$' | head
2026-09-28 15:47:14     634356 capture/20e4425092f90c7f/pod/AllTraffic/2026/09/28/15/28-15-47-12-999-ac31d31b-5156-46ad-9ccc-e8a040ab9ab2.jsonl
在 {s3Uri}/{uniqueID}/pod/{variant}/{YYYY}/{MM}/{DD}/{HH}/ 下會看到一個或多個 .jsonl 物件。每個 endpoint 都會產生 uniqueID。每一行都是一次推理,格式如下所示,為 SageMaker 的資料擷取格式。
擷取記錄的格式
請求和回應本文會以 base64 編碼方式儲存,如 encoding 欄位所示;因此讀取時須先進行 base64 解碼,再剖析 JSON:
{
  "captureData": {
    "endpointInput":  { "observedContentType": "application/json", "mode": "INPUT",
                        "data": "eyJtb2RlbCI6ICJyb3V0ZXItZnJlc2giLCAidGVtcGVyYXR1cmUiOiAwLCAi...", "encoding": "BASE64" },
    "endpointOutput": { "observedContentType": "application/json", "mode": "OUTPUT",
                        "data": "eyJpZCI6ImNoYXRjbXBsLTctMTc5MDYxMDM2OS4wMDUtMjMxMiIsIm9iamVj...", "encoding": "BASE64" }
  },
  "eventMetadata": { "eventId": "26859f07-d60b-4683-94aa-d21e7f19e746", "inferenceTime": "2026-09-28T15:46:09Z" },
  "eventVersion": "0"
}解碼後,endpointInput.data 是用戶端傳送的請求本文,endpointOutput.data 則是模型傳回的回應。
情境:支援工單路由器遇上產品推出
部署的模型是家電零售商的支援工單路由器。它使用 vLLM 引導式 JSON 解碼,將每張工單分類為六個類別之一:ProductFridge、ProductWasher、ProductOven、ProductDishwasher、ProductMicrowave,或兜底類別 Other。引導式解碼表示它只能傳回含有上述其中一個標籤的有效物件:
{"category": "ProductWasher", "confidence": 1}部署模型後,零售商推出了自家冷氣機系列 Arctis(Arctis 9K、12K、Mini 等)。路由器沒有適用於這些產品的類別。它無法説「這是新產品」,只能選擇它已知標籤中最接近的一個。除非記錄每個請求和回應,否則回應傳回後,相關證據便會消失。
合成流量
我們產生了兩個合成數據集:
- 正式環境流量:900 張工單,使用路由器原本的六標籤提示詞,按順序經由擷取代理重播,歷時 15 分鐘。前 400 張在產品推出前,沒有提及冷氣機。其餘 500 張中,Arctis 工單所佔比例由 15% 逐步升至 55%。
- 評估集:280 張已標記的工單,每個類別 40 張,包括新的
ProductAC。此評估集按內容留出:其中使用的症狀、句子範本及 Arctis 型號名稱,均未在流量中出現。
每個正式環境請求如下(系統提示詞已省略部分內容):
{"model": "appliance-router", "temperature": 0, "max_tokens": 40,
 "messages": [{"role": "system", "content": "You are a support-ticket router for a home-appliance retailer. ... category is one of: ProductFridge, ProductWasher, ProductOven, ProductDishwasher, ProductMicrowave, Other. ..."},
              {"role": "user", "content": "Hi, our Arctis 12K blows warm air since last week. Order #66759."}],
 "guided_json": {"type": "object", "required": ["category", "confidence"],
                 "properties": {"category": {"enum": ["ProductFridge", "ProductWasher", "ProductOven",
                                                      "ProductDishwasher", "ProductMicrowave", "Other"]},
"confidence": {"type": "number"}}}}要重播流量,請複製隨附的程式碼儲存庫、產生數據集,並透過擷取代理傳送數據。scripts/pod.sh 會在模型容器內執行用戶端,因此無需負載平衡器或 DNS。用戶端會列印 Athena 步驟所用的三個時間戳記:RUN_START、LAUNCH_TS(產品推出後的第一張工單)和 RUN_END。
git clone https://github.com/awslabs/awsome-distributed-ai.git
cd awsome-distributed-ai/examples/use-cases/sagemaker-hyperpod-data-capture-flywheel
(cd data && python3 ../scripts/gen_dataset.py)
scripts/pod.sh $ENDPOINT_NAME drive /tmp/tickets_traffic.jsonl --seconds 900
RUN_START=2026-09-28 15:52:40
  sent 100/900
...
LAUNCH_TS=2026-09-28 15:59:20
...
RUN_END=2026-09-28 16:07:40
匯出執行時列印的三個值,並等待一個緩衝區清空週期:
export RUN_START="2026-09-28 15:52:40" LAUNCH_TS="2026-09-28 15:59:20" RUN_END="2026-09-28 16:07:40"
sleep 75    # one flush interval
使用 Amazon Athena 揭示問題
產品推出後,離線基準測試看起來仍未改變,因為它們反映的是過去狀況。只有在擷取的正式環境流量中,才能看到這種變化。本節説明數據科學家如何使用 Athena 找出問題,無需佈建任何基礎設施。
步驟 6:設定變數並配置 Athena 輔助函式
export ATHENA_DB="flywheel_demo"
export ATHENA_OUTPUT="s3://${BUCKET}/athena-results/"
# Each endpoint writes under its own uniqueID. Pick the prefix whose captured requests name this
# endpoint, not whichever prefix sorts first (the Step 15 endpoint adds a second one).
for id in $(aws s3 ls "s3://${BUCKET}/capture/" | awk '/PRE/{print $2}'); do
  key=$(aws s3 ls "s3://${BUCKET}/capture/${id}pod/AllTraffic/" --recursive | awk '/\.jsonl$/{print $4; exit}')
  [ -n "$key" ] || continue
  model=$(aws s3 cp "s3://${BUCKET}/${key}" - 2>/dev/null | head -n 1 | python3 -c 'import sys, json, base64; r = json.loads(sys.stdin.readline()); print(json.loads(base64.b64decode(r["captureData"]["endpointInput"]["data"]))["model"])')
  if [ "$model" = "$ENDPOINT_NAME" ]; then export CAPTURE_LOCATION="s3://${BUCKET}/capture/${id}pod/AllTraffic/"; break; fi
done
echo "$CAPTURE_LOCATION"     # s3://<bucket>/capture/<uniqueID>/pod/AllTraffic/

# run_athena "<SQL>": runs one statement, prints tab-separated rows, and sets LAST_QID
run_athena() {
  local qid st
  qid=$(aws athena start-query-execution --query-string "$1" \
        --query-execution-context "Database=$ATHENA_DB" \
        --result-configuration "OutputLocation=$ATHENA_OUTPUT" \
        --output text --query 'QueryExecutionId') || return 1
  while :; do
    st=$(aws athena get-query-execution --query-execution-id "$qid" \
         --output text --query 'QueryExecution.Status.State')
    case "$st" in
      SUCCEEDED) break ;;
      FAILED|CANCELLED) aws athena get-query-execution --query-execution-id "$qid" \
          --output text --query 'QueryExecution.Status.StateChangeReason' >&2; return 1 ;;
    esac
    sleep 2
  done
  LAST_QID=$qid
  aws athena get-query-results --query-execution-id "$qid" \
    --output text --query 'ResultSet.Rows[*].Data[*].VarCharValue'
}
run_athena "CREATE DATABASE IF NOT EXISTS ${ATHENA_DB}"
步驟 7:向 Athena 宣告擷取資料(兩個層次)
第一層是外層封裝。外部資料表描述每筆記錄的外層 JSON,而對 year/month/day/hour 使用分區投影,便可將每小時的 S3 前綴對應至分區,無需爬蟲或 ADD PARTITION。data 欄位會宣告為一般字串,因為其內容是 base64 文字。
run_athena "
CREATE EXTERNAL TABLE IF NOT EXISTS inference_captures (
  captureData struct<
    endpointInput:  struct<observedContentType: string, mode: string, data: string, encoding: string>,
    endpointOutput: struct<observedContentType: string, mode: string, data: string, encoding: string>
  >,
  eventMetadata struct<eventId: string, inferenceTime: string>,
  eventVersion string
)
PARTITIONED BY (year string, month string, day string, hour string)
ROW FORMAT SERDE 'org.openx.data.jsonserde.JsonSerDe'
LOCATION '${CAPTURE_LOCATION}'
TBLPROPERTIES (
  'projection.enabled'='true',
  'projection.year.type'='integer',  'projection.year.range'='2026,2035',
  'projection.month.type'='integer', 'projection.month.range'='1,12', 'projection.month.digits'='2',
  'projection.day.type'='integer',   'projection.day.range'='1,31',   'projection.day.digits'='2',
  'projection.hour.type'='integer',  'projection.hour.range'='0,23',  'projection.hour.digits'='2',
  'storage.location.template'='${CAPTURE_LOCATION}\${year}/\${month}/\${day}/\${hour}/'
)"第二層是檢視,負責將每筆記錄解碼一次。from_utf8(from_base64(...)) 會將酬載還原為 JSON。若沒有它,每次擷取都會傳回 NULL。工單內容位於用戶訊息(messages[1])中,因為 messages[0] 是系統提示詞。模型答案是回應 JSON 內的 JSON 字串,因此需要再擷取一次。
run_athena "
CREATE OR REPLACE VIEW preds AS
WITH decoded AS (
  SELECT CAST(from_iso8601_timestamp(eventMetadata.inferenceTime) AS timestamp) AS ts,
         from_utf8(from_base64(captureData.endpointInput.data))  AS req,
         from_utf8(from_base64(captureData.endpointOutput.data)) AS resp
  FROM inference_captures
  WHERE year = '${RUN_START:0:4}' AND month = '${RUN_START:5:2}' AND day = '${RUN_START:8:2}'
)
SELECT ts,
       json_extract_scalar(req, '\$.messages[1].content') AS ticket_text,
       json_extract_scalar(json_extract_scalar(resp, '\$.choices[0].message.content'), '\$.category') AS predicted_category,
       CAST(json_extract_scalar(json_extract_scalar(resp, '\$.choices[0].message.content'), '\$.confidence') AS double) AS confidence
FROM decoded
WHERE ts >= timestamp '${RUN_START}' AND ts < timestamp '${RUN_END}'
"
run_athena "SELECT count(*) AS n, count_if(predicted_category IS NULL) AS unparsed FROM preds"
n   unparsed
900 0
關於檢視,有兩點須注意:
- 務必按分區篩選。Athena 會讀取原始 JSON,因此查詢若沒有分區篩選,就會掃描所有曾擷取的物件。此檢視會篩選至單日,而時間範圍則將資料限制在本次流量重播:同一個前綴亦包含步驟 5 的請求。
messages[1]假設只有一則系統訊息,後接一則用戶訊息。捕獲的流量反映用戶端實際送出的內容,因此如要處理多輪或少樣本請求,請相應調整擷取方式。
第 8 步:類別分佈有變化嗎?
run_athena "
SELECT date_trunc('minute', ts) AS minute, count(*) AS tickets,
       count_if(predicted_category = 'Other') AS other,
       round(100.0 * count_if(predicted_category = 'Other') / count(*), 1) AS other_pct
FROM preds GROUP BY 1 ORDER BY 1"
minute                   tickets  other  other_pct
2026-09-28 15:52:00.000       20      0        0.0
2026-09-28 15:53:00.000       60      3        5.0
2026-09-28 15:54:00.000       60      4        6.7
2026-09-28 15:55:00.000       60      4        6.7
2026-09-28 15:56:00.000       60      2        3.3
2026-09-28 15:57:00.000       60      1        1.7
2026-09-28 15:58:00.000       60      3        5.0
2026-09-28 15:59:00.000       60      9       15.0
2026-09-28 16:00:00.000       60     17       28.3
2026-09-28 16:01:00.000       60     14       23.3
2026-09-28 16:02:00.000       60     19       31.7
2026-09-28 16:03:00.000       60     21       35.0
2026-09-28 16:04:00.000       60     20       33.3
2026-09-28 16:05:00.000       60     32       53.3
2026-09-28 16:06:00.000       60     28       46.7
2026-09-28 16:07:00.000       40     26       65.0
(輸出以定位字元分隔。我們在此調整了排版,方便閲讀。這次執行將「數週」壓縮至 15 分鐘。在正式環境中,請按 date_trunc('day', ts) 或 'week' 分組。)
下圖以柱形表示每分鐘送往 Other 的工單佔比,並以折線表示累計佔比,另標示推出時間。
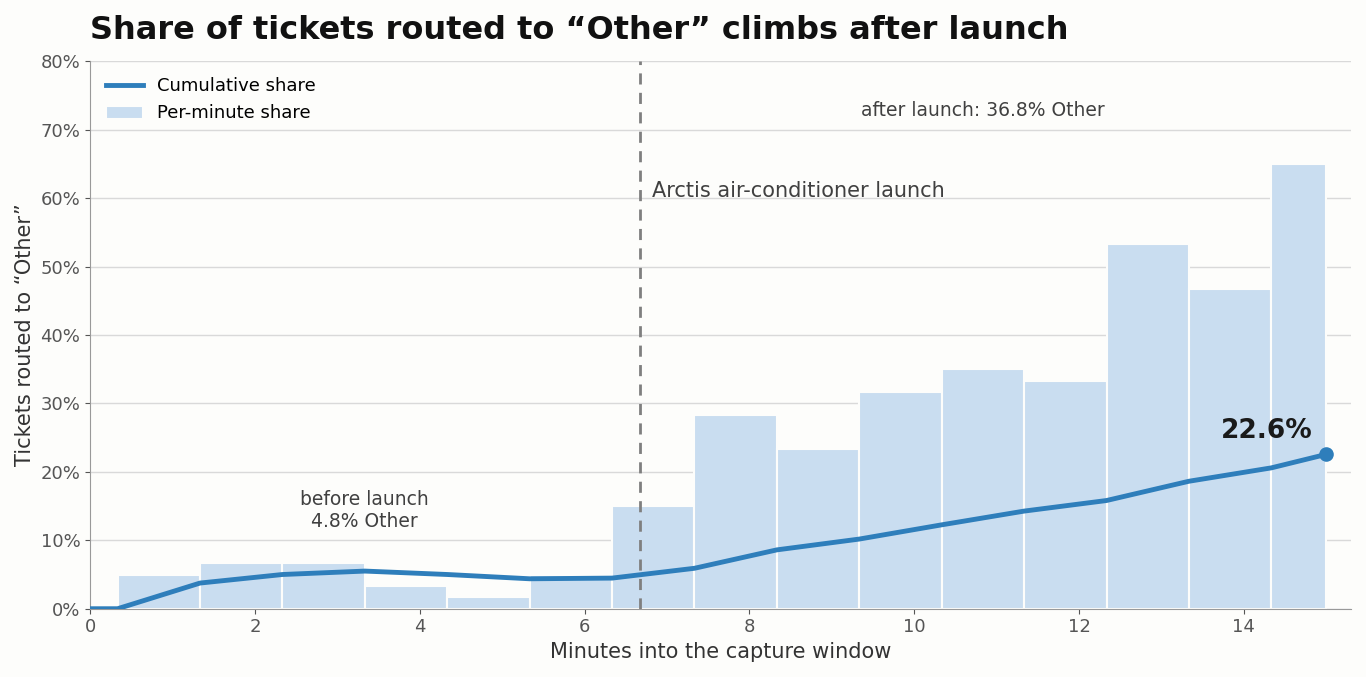
圖 2:Arctis 推出前後,送往「其他」的工單每分鐘及累計佔比
推出前,Other每分鐘佔比低於 7%。推出當分鐘,佔比躍升至 15%,之後持續上升,最後三分鐘達到 47–65%。圖中的累計折線僅達 22.6%,因為它將推出後的工單與推出前的所有流量一併計算。這就是為何應以每分鐘比率,而非累計佔比作為警報依據。
按推出時間點分開後,整體類別分佈如下:
run_athena "
SELECT IF(ts < timestamp '${LAUNCH_TS}', '1-before launch', '2-after launch') AS period,
       predicted_category, count(*) AS n
FROM preds GROUP BY 1, 2 ORDER BY 1, 3 DESC"
period           predicted_category    n
1-before launch  ProductFridge        91
1-before launch  ProductWasher        83
1-before launch  ProductDishwasher    74
1-before launch  ProductOven          74
1-before launch  ProductMicrowave     59
1-before launch  Other                19
2-after launch   Other               184
2-after launch   ProductFridge        84
2-after launch   ProductOven          66
2-after launch   ProductDishwasher    64
2-after launch   ProductWasher        58
2-after launch ProductMicrowave 44Other在推出前佔工單的 4.8%(400 張中有 19 張),推出後則升至 36.8%(500 張中有 184 張),成為最大類別。
第 9 步:「其他」類別中有甚麼?
run_athena "
SELECT word, count(*) AS freq
FROM preds CROSS JOIN UNNEST(regexp_extract_all(lower(ticket_text), '[a-z0-9-]{4,}')) AS t(word)
WHERE predicted_category = 'Other'
  AND word NOT IN ('this','that','with','from','have','since','week','help','need','again','time',
                   'month','second','take','look','someone','order','last','after','when','onto')
GROUP BY 1 ORDER BY 2 DESC, 1 LIMIT 10"
word      freq
arctis     141
unit        40
mini        33
cooling     30
link        30
lost        30
loudly      30
rattles     30
wi-fi       30
blows 28Other類別並非由互不相關的工單組成。當中主要是單一產品名稱 arctis 及冷氣設備相關詞彙,顯示出現了一個路由模型沒有對應標籤的新類別。
第 10 步:規模有多大?模型的信心度能否反映出來?
搜尋整個流量,找出新產品相關工單,而不只是搜尋 Other 類別:
run_athena "
SELECT IF(ts < timestamp '${LAUNCH_TS}', '1-before launch', '2-after launch') AS period,
       predicted_category, count(*) AS n
FROM preds WHERE regexp_like(lower(ticket_text), 'arctis|air condition')
GROUP BY 1, 2 ORDER BY 1, 3 DESC"
period          predicted_category    n
2-after launch  Other               164
2-after launch  ProductFridge        14
有 178 張冷氣機工單,佔整體流量的 19.8%。推出前一張也沒有。這些工單分為兩組:
- 164 張被分到
Other。在六個標籤的分類架構下,這是正確答案:Other正是為這種情況而設。路由模型沒有故障;分類體系缺少一個類別,因此這些工單被送到一般隊列,而非負責支援該產品的團隊。 - 14 張被分到
ProductFridge。這些才是真正的錯誤路由:冰箱支援團隊現在收到冷氣機工單。
現在測試模型對這些已知錯誤路由工單的信心度:
run_athena "
SELECT predicted_category, confidence, count(*) AS n FROM preds
WHERE regexp_like(lower(ticket_text), 'arctis|air condition')
GROUP BY 1, 2 ORDER BY 1, 2 DESC"
predicted_category  confidence    n
Other                      1.0  157
Other                      0.9    7
ProductFridge             0.95    1
ProductFridge              0.9    9
ProductFridge              0.8    2
ProductFridge              0.7    1
ProductFridge              0.0    1
14 張錯誤路由工單中,有 10 張回報的信心度為 0.9 或以上。若採用「保留符合 confidence >= 0.9 條件的預測」等標註規則,便會保留 71% 已知錯誤的標籤。這是因為 confidence 是我們要求模型輸出的欄位,而非經校準的機率。如需真正的不確定性指標,可向 vLLM 要求 token logprobs,並讀取類別 token 的機率,而非採用模型自行回報的數值。請預留額外資料負載所需的容量,因為每次回應都會擷取 logprobs。
從診斷到已標註的訓練資料
資料科學家不會逐一為數百張工單手動標註,而是將 Athena 的發現整理成一套標註政策:一個 SQL 檢視,為每筆捕獲記錄指派修正後的標籤。我們將錯誤路由的冷氣機工單重新標註為新類別。
第 11 步:標註政策
run_athena "
CREATE OR REPLACE VIEW labeled_training_data AS
WITH t AS (SELECT ticket_text, predicted_category, lower(ticket_text) AS txt FROM preds)
SELECT ticket_text, predicted_category,
  CASE
    -- 1. The new class, identified by keyword evidence, not by what the model predicted
    WHEN regexp_like(txt, '\\barctis\\b|air condition|\\bac unit\\b|mini split')
     AND NOT regexp_like(txt, 'fridge|refrigerat|freezer|washer|\\boven\\b|\\brange\\b|dishwasher|microwave')
      THEN 'ProductAC'
    -- 2. Keep the production decision when nothing hints at the new product
    WHEN NOT regexp_like(txt, '\\barctis\\b|air condition|\\bac\\b|mini split')
      THEN predicted_category
    -- 3. Mixed signals: send to human review (Amazon SageMaker Ground Truth)
    ELSE NULL
  END AS corrected_category
FROM t"雙反斜線(\\b)是在雙引號字串內的 Shell 跳脱處理。Athena 收到的是 \b,即正規表示式中的字詞邊界。
查看政策產生的結果:
run_athena "
SELECT coalesce(corrected_category, '(human review)') AS label, count(*) AS n,
       count(DISTINCT ticket_text) AS distinct_texts,
       count_if(corrected_category <> predicted_category) AS relabeled
FROM labeled_training_data GROUP BY 1 ORDER BY 2 DESC"
label               n    distinct_texts  relabeled
ProductAC         178               114        178
ProductFridge     161               110          0
ProductWasher     141                96          0
ProductOven       140                97          0
ProductDishwasher 138                95          0
ProductMicrowave  103                82          0
Other              39                 8          0
這個啟發式方法之所以有效,是因為新類別界線清晰(可透過關鍵字識別)。對於含糊不清的工單或類別重疊的情況,NULL 列會送往 Ground Truth,由人手標註。
第 12 步:建立訓練檔案
匯出已加上標籤的檢視,並將其轉換為對話格式 JSONL。允許的類別集合現已包括 ProductAC,即重新部署後用戶端會傳送的同一份七標籤提示詞。將其儲存為 build_training_file.py:
cat > build_training_file.py <<'PY'
import csv, json, sys
CATS = ["ProductFridge", "ProductWasher", "ProductOven", "ProductDishwasher", "ProductMicrowave", "ProductAC", "Other"]
PROMPT = ("You are a support-ticket router for a home-appliance retailer. Route each ticket to the product it "
          'concerns. Respond with ONLY a JSON object {"category": "...", "confidence": <0-1>} where category is '
          "one of: " + ", ".join(CATS) + '. Use "Other" if the ticket does not clearly concern one of these products.')
n = 0
with open(sys.argv[1], newline="") as fin, open(sys.argv[2], "w") as fout:
    for row in csv.DictReader(fin):
        fout.write(json.dumps({"messages": [
            {"role": "system", "content": PROMPT},
            {"role": "user", "content": row["ticket_text"]},
            {"role": "assistant", "content": json.dumps({"category": row["corrected_category"], "confidence": 1.0})},
        ]}) + "\n"); n += 1
print(f"wrote {n} training examples -> {sys.argv[2]}")
PY

run_athena "SELECT ticket_text, corrected_category FROM labeled_training_data
            WHERE corrected_category IS NOT NULL" > /dev/null
aws s3 cp "${ATHENA_OUTPUT}${LAST_QID}.csv" labeled.csv --only-show-errors   # Athena's own CSV: header + proper quoting
python3 build_training_file.py labeled.csv train.jsonl
aws s3 cp train.jsonl "s3://${BUCKET}/training/train.jsonl"
wrote 900 training examples -> train.jsonl
使用 HyperPod 訓練運算子對擷取的數據進行微調
我們在提供模型服務的同一個叢集上進行微調,使用 HyperPod 訓練運算子和第二個 GPU。第一個端點會全程繼續提供服務。
步驟 13:訓練指令碼
指令碼會從 S3 下載基礎模型和訓練數據,並訓練低秩適應(LoRA)適配器。損失只會根據助理回合計算,因此模型學會輸出標籤,而不是重複提示詞。接着,指令碼會將適配器合併回基礎模型的權重,讓 vLLM 無需變更即可提供合併後的模型服務,並將模型上載至 S3。工作會透過 ConfigMap 將指令碼掛載至訓練 Pod。
cat > train.py <<'PY'
import os, boto3, torch
from datasets import load_dataset
from peft import LoraConfig, get_peft_model
from transformers import AutoModelForCausalLM, AutoTokenizer, Trainer, TrainingArguments

s3 = boto3.client("s3")
def split(uri): b, _, k = uri[5:].partition("/"); return b, k

# 1. Stage base model + training data from S3
bucket, prefix = split(os.environ["BASE_MODEL_S3"])
for page in s3.get_paginator("list_objects_v2").paginate(Bucket=bucket, Prefix=prefix):
    for o in page.get("Contents", []):
        dst = os.path.join("/work/base", os.path.relpath(o["Key"], prefix))
        os.makedirs(os.path.dirname(dst), exist_ok=True); s3.download_file(bucket, o["Key"], dst)
s3.download_file(*split(os.environ["TRAIN_FILE_S3"]), "/work/train.jsonl")
print("[stage] base model and training data downloaded", flush=True)

# 2. LoRA SFT, loss only on the assistant turn (the label), not the prompt
tok = AutoTokenizer.from_pretrained("/work/base")
def encode(ex):
    full = tok.apply_chat_template(ex["messages"], tokenize=False)
    prompt = tok.apply_chat_template(ex["messages"][:-1], tokenize=False, add_generation_prompt=True)
    ids = tok(full, add_special_tokens=False)["input_ids"]
    n = len(tok(prompt, add_special_tokens=False)["input_ids"])
    return {"input_ids": ids, "labels": [-100] * n + ids[n:]}
ds = load_dataset("json", data_files="/work/train.jsonl", split="train")
print(f"[data] {len(ds)} examples", flush=True)
ds = ds.map(encode, remove_columns=ds.column_names)

def collate(batch):
    m = max(len(b["input_ids"]) for b in batch)
    pad = lambda xs, v: [x + [v] * (m - len(x)) for x in xs]
    return {"input_ids": torch.tensor(pad([b["input_ids"] for b in batch], tok.pad_token_id)),
            "labels": torch.tensor(pad([b["labels"] for b in batch], -100)),
            "attention_mask": torch.tensor(pad([[1] * len(b["input_ids"]) for b in batch], 0))}

model = AutoModelForCausalLM.from_pretrained("/work/base", torch_dtype=torch.bfloat16, device_map="cuda:0")
model = get_peft_model(model, LoraConfig(r=16, lora_alpha=32, lora_dropout=0.05, task_type="CAUSAL_LM",
    target_modules=["q_proj", "k_proj", "v_proj", "o_proj", "gate_proj", "up_proj", "down_proj"]))
model.print_trainable_parameters()
Trainer(model=model, train_dataset=ds, data_collator=collate, args=TrainingArguments(
    output_dir="/tmp/ckpt", num_train_epochs=float(os.getenv("EPOCHS", "2")), learning_rate=1e-4,
    per_device_train_batch_size=8, bf16=True, logging_steps=10, save_strategy="no", report_to=[],
    warmup_ratio=0.1, lr_scheduler_type="cosine")).train()

# 3. Merge the adapter into the base weights (a plain model vLLM can serve) and upload it
model.merge_and_unload().save_pretrained("/work/out", safe_serialization=True)
tok.save_pretrained("/work/out")
bucket, prefix = split(os.environ["OUTPUT_S3"])
for f in os.listdir("/work/out"):
    s3.upload_file(os.path.join("/work/out", f), bucket, f"{prefix.rstrip('/')}/{f}")
print(f"[done] merged model uploaded to {os.environ['OUTPUT_S3']}", flush=True)
PY
kubectl create configmap router-train --from-file=train.py
步驟 14:提交 HyperPodPyTorchJob
cat > finetune-job.yaml <<'YAML'
apiVersion: sagemaker.amazonaws.com/v1
kind: HyperPodPyTorchJob
metadata:
  name: router-ft
  namespace: default
spec:
  nprocPerNode: "1"
  runPolicy:
    jobMaxRetryCount: 2
    cleanPodPolicy: All              # release the GPU as soon as the job finishes
    logMonitoringConfiguration:      # restart a job that never starts, or goes quiet mid-run
      - name: JobStart
        logPattern: '.*loss.*'
        expectedStartCutOffInSeconds: 1200
      - name: JobHangingDetection
        logPattern: '.*loss.*'
        expectedRecurringFrequencyInSeconds: 600
  replicaSpecs:
    - name: pod
      replicas: 1
      template:
        metadata:
          labels: { app: router-ft }
        spec:
          serviceAccountName: ${TRAIN_SA}        # EKS Pod Identity -> S3 read/write
          nodeSelector:
            node.kubernetes.io/instance-type: ${TRAIN_INSTANCE_TYPE}
          restartPolicy: Always                  # required by the operator; retries live in runPolicy
          containers:
            - name: pytorch
              image: vllm/vllm-openai:v0.10.0    # already has torch + transformers + boto3
              command: ["bash", "-c"]
              args:
                - pip install -q peft==0.14.0 datasets==3.2.0 hyperpod-elastic-agent==1.1.3 &&
                  hyperpodrun --nnodes=1 --nproc_per_node=1 /scripts/train.py
              env:
                - { name: BASE_MODEL_S3, value: "s3://${BUCKET}/${MODEL_LOCATION}/" }
                - { name: TRAIN_FILE_S3, value: "s3://${BUCKET}/training/train.jsonl" }
                - { name: OUTPUT_S3,     value: "s3://${BUCKET}/${MODEL_V2_LOCATION}/" }
              resources:
                requests: { cpu: "2", memory: 24Gi, nvidia.com/gpu: 1 }
                limits:   { nvidia.com/gpu: 1 }
              volumeMounts:
                - { name: scripts, mountPath: /scripts }
                - { name: work,    mountPath: /work }
                - { name: shm,     mountPath: /dev/shm }
          volumes:
            - { name: scripts, configMap: { name: router-train } }
            - { name: work,    emptyDir: {} }
            - { name: shm,     emptyDir: { medium: Memory, sizeLimit: 8Gi } }
YAML
render < finetune-job.yaml | kubectl apply -f -
kubectl logs -l app=router-ft -flogMonitoringConfiguration是訓練運算子的識別特徵。如果開始後 20 分鐘內沒有出現loss這一行,或執行期間程序仍在運作但日誌靜默 10 分鐘,運算子便會重新啟動工作,而不是任由它耗用 GPU 時數。- 工作啟動時會安裝三個 Python 套件。訓練節點需要連線至外部互聯網,例如透過 NAT 閘道;從 Docker Hub 拉取
vllm/vllm-openai映像檔亦需要外連網絡。在無法連線至外部互聯網的叢集上,請將套件預先整合至 Amazon Elastic Container Registry (Amazon ECR) 的自訂映像檔,並移除pip install。
工作日誌摘錄:
{'loss': 0.2484, 'grad_norm': 3.387, 'learning_rate': 3.91e-05, 'epoch': 0.09}
{'loss': 0.018, 'grad_norm': 0.0037, 'learning_rate': 8.26e-05, 'epoch': 0.18}
...
{'loss': 0.0, 'grad_norm': 0.000105, 'learning_rate': 2.93e-07, 'epoch': 1.95}
{'train_runtime': 59.68, 'train_samples_per_second': 30.16, 'train_loss': 0.0123, 'epoch': 2.0}
[done] merged model uploaded to s3://amzn-s3-demo-bucket/models/qwen2.5-3b-router-v2/
[HyperPodElasticAgent] ... Transitioned from AgentState.RUNNING to AgentState.COMPLETED
kubectl get hyperpodpytorchjob router-ft -o jsonpath='{range .status.conditions[*]}=  {end}'
Created=True  Completed=True
使用一部 L40S 訓練只需60 秒。LoRA 的秩為 16,訓練約 29.9 million 個參數,不足 3.1-billion-parameter 模型的 1%。平均訓練損失為 0.0123,每步損失在第一個 epoch 內便降至 0.0,顯示模型很容易記住 900 個範本化例子。使用真實數據時,應留出驗證集並提早停止訓練。此處我們依靠留出的評估集。
步驟 15:保持擷取功能開啟,同時並行部署微調後的模型
不要修改正在運作的端點,而是使用同一份 manifest,將新模型部署為第二個端點,並使用訓練工作剛釋出的 GPU。第一個端點會繼續提供服務,直至你切換用戶端,因此重新部署不會造成停機;如要回復,只需讓用戶端重新指向第一個端點。
export ENDPOINT_NAME="appliance-router-v2" MODEL_LOCATION="$MODEL_V2_LOCATION" SERVE_INSTANCE_TYPE="$TRAIN_INSTANCE_TYPE"
render < endpoint.yaml | kubectl apply -f -
kubectl get pods -l app=$ENDPOINT_NAME -o custom-columns='NAME:.metadata.name,READY:.status.containerStatuses[*].ready,NODE:.spec.nodeName'
NAME                                  READY                 NODE
appliance-router-v2-c96594c5-fhs2x    true,true,true,true   hyperpod-i-0e0b756209b5e497a
新端點會將擷取資料寫入自己的 uniqueID。由於 ENDPOINT_NAME 現在是 appliance-router-v2,重新執行步驟 6 的 CAPTURE_LOCATION 查詢便會找到該前綴,因此你可以建立第二個 Athena 資料表並將其指向該前綴,以便進行下一輪分析。切換用戶端時,請在同一個版本發佈中更新端點、標籤集合和 guided-JSON 列舉值。
衡量提升幅度
我們使用相同的 280 張留出工單,測試微調後的端點:
overall 280/280 = 100.00%
  ProductFridge      40/40
  ProductWasher      40/40
  ProductOven        40/40
  ProductDishwasher  40/40
  ProductMicrowave   40/40
  ProductAC          40/40
Other 40/40| 指標 | 微調前(剛推出時) | 微調後 |
| 留出集準確率(280) | 235 (83.9%) | 280 (100%) |
ProductAC(40) |
0/40 — 全部均分流至 Other |
40/40 |
Other(40) |
35/40 | 40/40 |
| 五個既有產品類別(200) | 200/200 | 200/200 |
| 手寫探測工單(24,以下詳述) | 16/24 | 20/24 |
微調令路由模型學會新的類別,亦沒有令五個既有類別的表現倒退。此外,微調亦修正了正式推出前已存在的五個 Other 錯誤;當時推出的路由模型會將這些錯誤分流至 ProductFridge。
由於評估集和訓練數據來自同一個產生器,我們亦手寫了 24 張探測工單,採用產生器從未生成過的寫法。微調後的模型得分為 20/24:
  MISS ProductFridge -> ProductAC: The cooling fan in my fridge is squealing.
  MISS Other -> ProductAC: When will the Arctis 12K be back in stock?
  MISS Other -> ProductAC: Can I get a quote to install central air in my house?
  MISS Other -> ProductAC: Do you price match the Arctis at other stores?
overall 20/24 = 83.33%
八個冷氣機測試樣本全部路由正確,但模型學到了兩個捷徑:「cooling」代表冷氣機,而任何提及 Arctis 的內容都代表 ProductAC,包括庫存及價格匹配問題。這兩個捷徑都源自訓練數據:標註政策將所有 Arctis 工單都送往 ProductAC,而擷取的流量中沒有售前問題。為新端點啟用資料擷取後,這些工單正是下一輪擷取會收集的內容。
資料擷取會增加多少延遲?
我們直接測量了延遲:在 pod 內發送同一批 400 個路由請求,分別使用連接埠 8000(未啟用資料擷取)或連接埠 8081(經由資料擷取 Proxy)。我們以 8 個並行請求執行三輪,另加一輪序列測試:
| 路徑 | 並行數 | p50 | p99 | 吞吐量 |
| 直接連至 vLLM (8000),未啟用資料擷取 | 8 | 200.7 ms | 249.4 ms | 39.1 req/s |
| 經由資料擷取 Proxy (8081) | 8 | 200.0 ms | 249.8 ms | 39.1 req/s |
| 直接連至 vLLM (8000),未啟用資料擷取 | 1 | 164.4 ms | 206.9 ms | 6.0 req/s |
| 經由資料擷取 Proxy (8081) | 1 | 164.4 ms | 207.0 ms | 6.0 req/s |
並行數為 8 的各列數據是三輪測試的平均值。每輪測試之間的差異(p50 為 ±1 ms)大於兩種路徑之間的差異。
擷取數據的其他用途
推理數據寫入 S3 後,同一批記錄可用於多種工作流程:
- 改進模型:使用監督式微調(如本文所示)、將大型模型的輸出蒸餾至較小模型,或建立偏好配對以進行直接偏好最佳化 (DPO)。
- 瞭解模型:執行 Athena 分析(如本文所示)、根據真實提示詞建立黃金回歸測試集、設定漂移警報、發現新興意圖,以及偵測格式錯誤的輸出和拒答。
- 營運及管治:將含糊不清的樣本送往 Ground Truth 進行標註、保留稽核記錄(建議使用 Tier 1)、重播事故所涉的確切輸入,以及分析流量和有效負載以歸屬成本。
成本考量
| 層級 | 大約成本影響 |
| 層級 1(SageMaker 端點) | 由 SageMaker 在端點擷取。你需要支付這些有效負載的 S3 儲存及請求費用 |
| 層級 2(ALB 存取日誌) | 只需支付日誌檔案的 S3 儲存費用 |
| 層級 3(模型 pod) | 三個 sidecar 每個 pod 合共要求 250m CPU + 640 MiB(NGINX Proxy 100m/128Mi、OTel 收集器 100m/256Mi、s3-uploader 50m/256Mi),另加有效負載的 S3 儲存及請求費用 |
兩項成本會隨用量變動:
- S3。我們的記錄平均每筆約 2.3 KB(9.0 MB 內有 3,955 筆記錄)。提示詞及回應越長,成本按比例越高。上載程式每個 pod 每個 flush 間隔寫入一個物件;間隔為 60 秒時,每個 pod 每日約有 1,440 次 PUT。
- Athena 按掃描的數據量收費,因此請務必按分割區欄位篩選;如需重複分析,請使用
CREATE TABLE AS SELECT(CTAS) 查詢將原始 JSON 轉換為 Parquet。
最新價格請參閲 Amazon S3 定價及 Amazon Athena 定價。
清理
為避免產生不必要的費用,請清理本教學建立的資源:
kubectl delete inferenceendpointconfig appliance-router appliance-router-v2
kubectl delete hyperpodpytorchjob router-ft
kubectl delete configmap router-train
run_athena "DROP VIEW IF EXISTS labeled_training_data"; run_athena "DROP VIEW IF EXISTS preds"
run_athena "DROP TABLE IF EXISTS inference_captures"; run_athena "DROP DATABASE IF EXISTS ${ATHENA_DB}"
aws s3 rm "s3://${BUCKET}/capture/" --recursive
aws s3 rm "s3://${BUCKET}/athena-results/" --recursive
aws s3 rm "s3://${BUCKET}/training/" --recursive
aws s3 rm "s3://${BUCKET}/${MODEL_V2_LOCATION}/" --recursive
結論
本文展示如何使用 SageMaker HyperPod Data Capture 記錄即時推理數據,並將其轉化為訓練數據。資料擷取可透過三個互相獨立的層級進行,你可以:
- 收集真實世界的訓練數據,且對服務延遲沒有可測量的影響。
- 使用 Amazon Athena 大規模查詢推理模式,無須管理基礎設施。
- 將 Athena 診斷結果轉化為可重現的 SQL 標註政策。
- 使用擷取的生產環境數據進行微調,並量度明確的前後提升。
- 與 HyperPod training operator 及 SageMaker Ground Truth 整合,完成其餘流程。
我們在家電客服路由器上完整執行了一輪流程。擷取的流量揭示了新產品盲點,而 SQL 標註政策則將這些擷取資料轉化為訓練數據。使用 HyperPod training operator 進行的 60 秒 LoRA 微調,在提供模型服務的同一個叢集上執行。新類別的召回率由 0% 提升至完全召回,現有類別的效能則沒有倒退。模型部署前,這些訓練數據全都不存在。
Data Capture 現已可在配備 inference operator 的 SageMaker HyperPod 叢集上使用。要開始使用,請在 InferenceEndpointConfig 或 JumpStartModel 資源中加入 dataCapture 區段,然後部署。要在同一個叢集上完成整個流程,請加入 amazon-sagemaker-hyperpod-training-operator EKS 附加元件。本教學的完整程式碼載於隨附的 GitHub 儲存庫。
如需更多資訊,請參閲SageMaker HyperPod 推理説明文件及HyperPod training operator 説明文件。
作者簡介

Shantanu Tripathi
Shantanu 是 AWS 的軟件開發工程師,具備建構大型 AI/ML 基礎設施的經驗。作為 Amazon SageMaker 的核心工程師,他曾負責設計及最佳化可擴展的推理方案,以支援高效能 AI 工作負載。他的其他工作經驗涵蓋分散式 AI 訓練程式庫、Deep Learning Containers (DLCs)、Deep Learning AMIs 及生成式 AI 方案。工作之餘,他喜歡戲劇和游泳。

Roy Allela
Roy 是 AWS 的首席 AI/ML 專業解決方案架構師。他與 AWS 客戶合作,客戶涵蓋初創公司至大型企業,協助他們在 AWS 上有效訓練及部署基礎模型。他具有微處理器工程背景,熱衷於計算最佳化問題,以及提升 AI 工作負載的效能。

Piyush Daftary
Piyush 是 AWS 的首席軟件工程師,負責 Amazon SageMaker,專注於為大型語言模型建構高效能、可擴展的推理系統。他的技術興趣涵蓋 AI/ML、資料庫及搜尋技術,專長是開發可投入生產環境使用的方案,實現大規模高效推理。他的工作包括最佳化系統效能、實作智能路由機制,以及設計支援研究和生產工作負載的架構。他熱衷於解決複雜的分散式系統難題,並讓開發人員和機構更容易使用先進的 AI 功能。工作之餘,他喜歡旅遊、遠足和與家人共度時光。

Sean Archer
Sean 是 AWS 的軟件開發工程師,負責為 Amazon SageMaker 建構 AI/ML 基礎設施。他曾參與開發支援可靠、可擴展模型部署的推理方案,以及 SageMaker HyperPod 叢集的運算資源治理功能,協助機構管理及分配大型 AI 工作負載所需的運算資源。工作之餘,他喜歡演奏音樂和旅遊。
來源:AWS Machine Learning Blog · aws.amazon.com