OlmoEarth v1.3 發佈全球衞星嵌入模型
OlmoEarth v1.3: State-of-the-art embeddings for the whole planet
OlmoEarth 發佈 v1.3 衞星嵌入模型,並提供全球預先計算的年度嵌入向量及 OlmoEarth Embeddings Explorer。模型為每個 10 米像素提供 128 維嵌入,亦可使用 64 維版本;在 27 項評測中,兩者分別於 20 項和 18 項評測表現領先,2023 至 2025 年的嵌入資料覆蓋全球。
這次發佈把全球預先計算的嵌入向量與免登入探索工具一併提供,讀者可瞭解如何免用 GPU 進行衞星資料比較和簡單分類。
🤗 Models | 📄 Tech Report | 📊 Data | 💻 Code | 🌎 Embeddings Explorer | 🗺️ Interactive story
Today, we’re releasing OlmoEarth v1.3, a state-of-the-art satellite embedding model. Alongside OlmoEarth v1.3, we’re sharing precomputed, annual embeddings for the whole planet (10m, 64- and 128-dimensions), plus a new browser-based tool to explore and customize maps based on those embeddings — the OlmoEarth Embeddings Explorer. This means anyone can put OlmoEarth v1.3 to work right away, from tracking change over time to finding similar places—no sign-in, and no advanced technical knowledge required.
Until now, the primary way to use OlmoEarth was fine-tuning in OlmoEarth Studio: training a model for each task and running it over satellite imagery to make a map. That requires GPU access and the ability to download and store the imagery. Embedding models compress satellite data into ready-to-use features that can be reused cheaply for many tasks.
With OlmoEarth v1.3, we’re excited to give users more ways to explore and engage with planetary artifacts in whatever way suits them best.
Compute once, reuse everywhere
An embedding represents what the model learned from millions of images. OlmoEarth v1.3 reads a year of radar (Sentinel-1) and multispectral (Sentinel-2 and Landsat) satellite time series and produces one 128-dimensional vector for every 10-meter pixel on Earth; the first 64 dimensions also work on their own as a smaller embedding.
Foundation models and global embeddings are expensive to produce, and to make sure everyone is able to access the benefits, we’ve computed these embeddings for the entire planet and shared them with the community on Source Cooperative. From there, a crop map, a land-cover map, or a change analysis becomes a lightweight modeling problem: train a small classifier on top and run it locally.
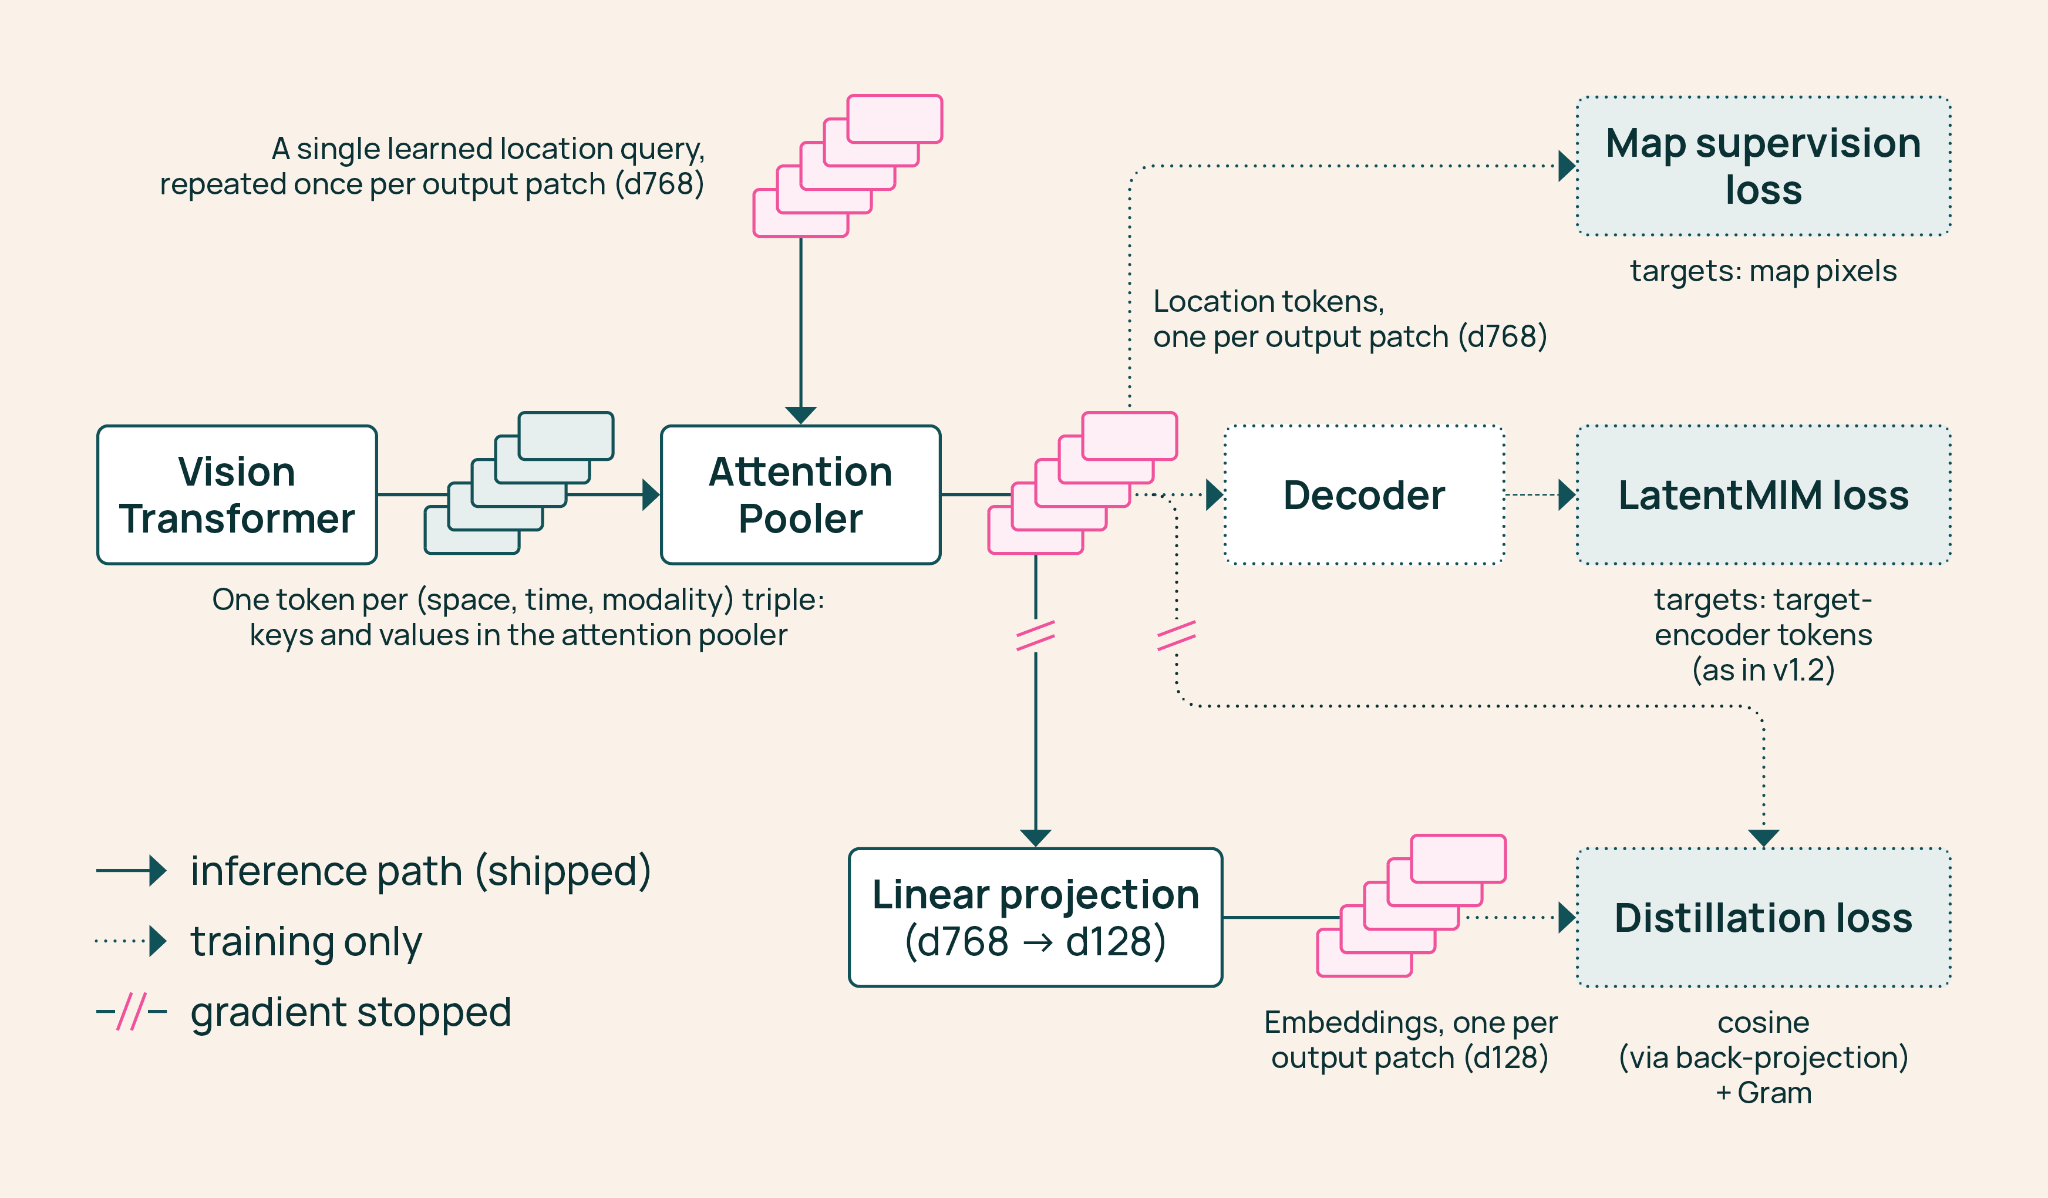
How OlmoEarth v1.3 makes an embedding: a vision transformer reads the satellite data, an Attention Pooler pools it into one vector per patch of land, and a linear layer reduces it to 128 numbers.
State-of-the-art embeddings
We evaluated OlmoEarth v1.3's embeddings against AlphaEarth Foundations (AEF) and Tessera v2 across 27 evaluations, covering six continents and many different tasks. OlmoEarth’s 128-dimensional embeddings score highest on 20 of 27 evals and rank highest overall. The 64-dimensional version, at half the size, still leads on 18 of 27 evals. As part of this evaluation, we introduce PLANTEUR, a new crop-type benchmark for tropical farming, and the embeddings generalize best to places a classifier has never seen (PLANTEUR technical report is available here). Everything behind them is fully open: the model weights, the pretraining data, and the pretraining code.
In practice, this means a small classifier trained on the OlmoEarth embeddings is enough to map what’s on the ground: think classifying smallholder crops in Kenya, detecting brick kilns west of Dhaka, assessing fire damage in Indonesia, and tracking gold mining in the Peruvian Amazon.
Compared to previous generations of OlmoEarth models, OlmoEarth v1.3 was also our cheapest model to train. It took 53% of the computing time of our last version (v1.2) and 18% of our first (v1), with 50% and 22% of the carbon emissions. And it also remains a strong fine-tuning model, matching v1.2's performance across research and partner labels. Our latest model builds on the same foundation as earlier OlmoEarth versions, tuned so the embeddings stay lightweight without giving up accuracy across tasks, and that efficiency work carries forward into the versions ahead.
Full results and methodology are in our technical report.
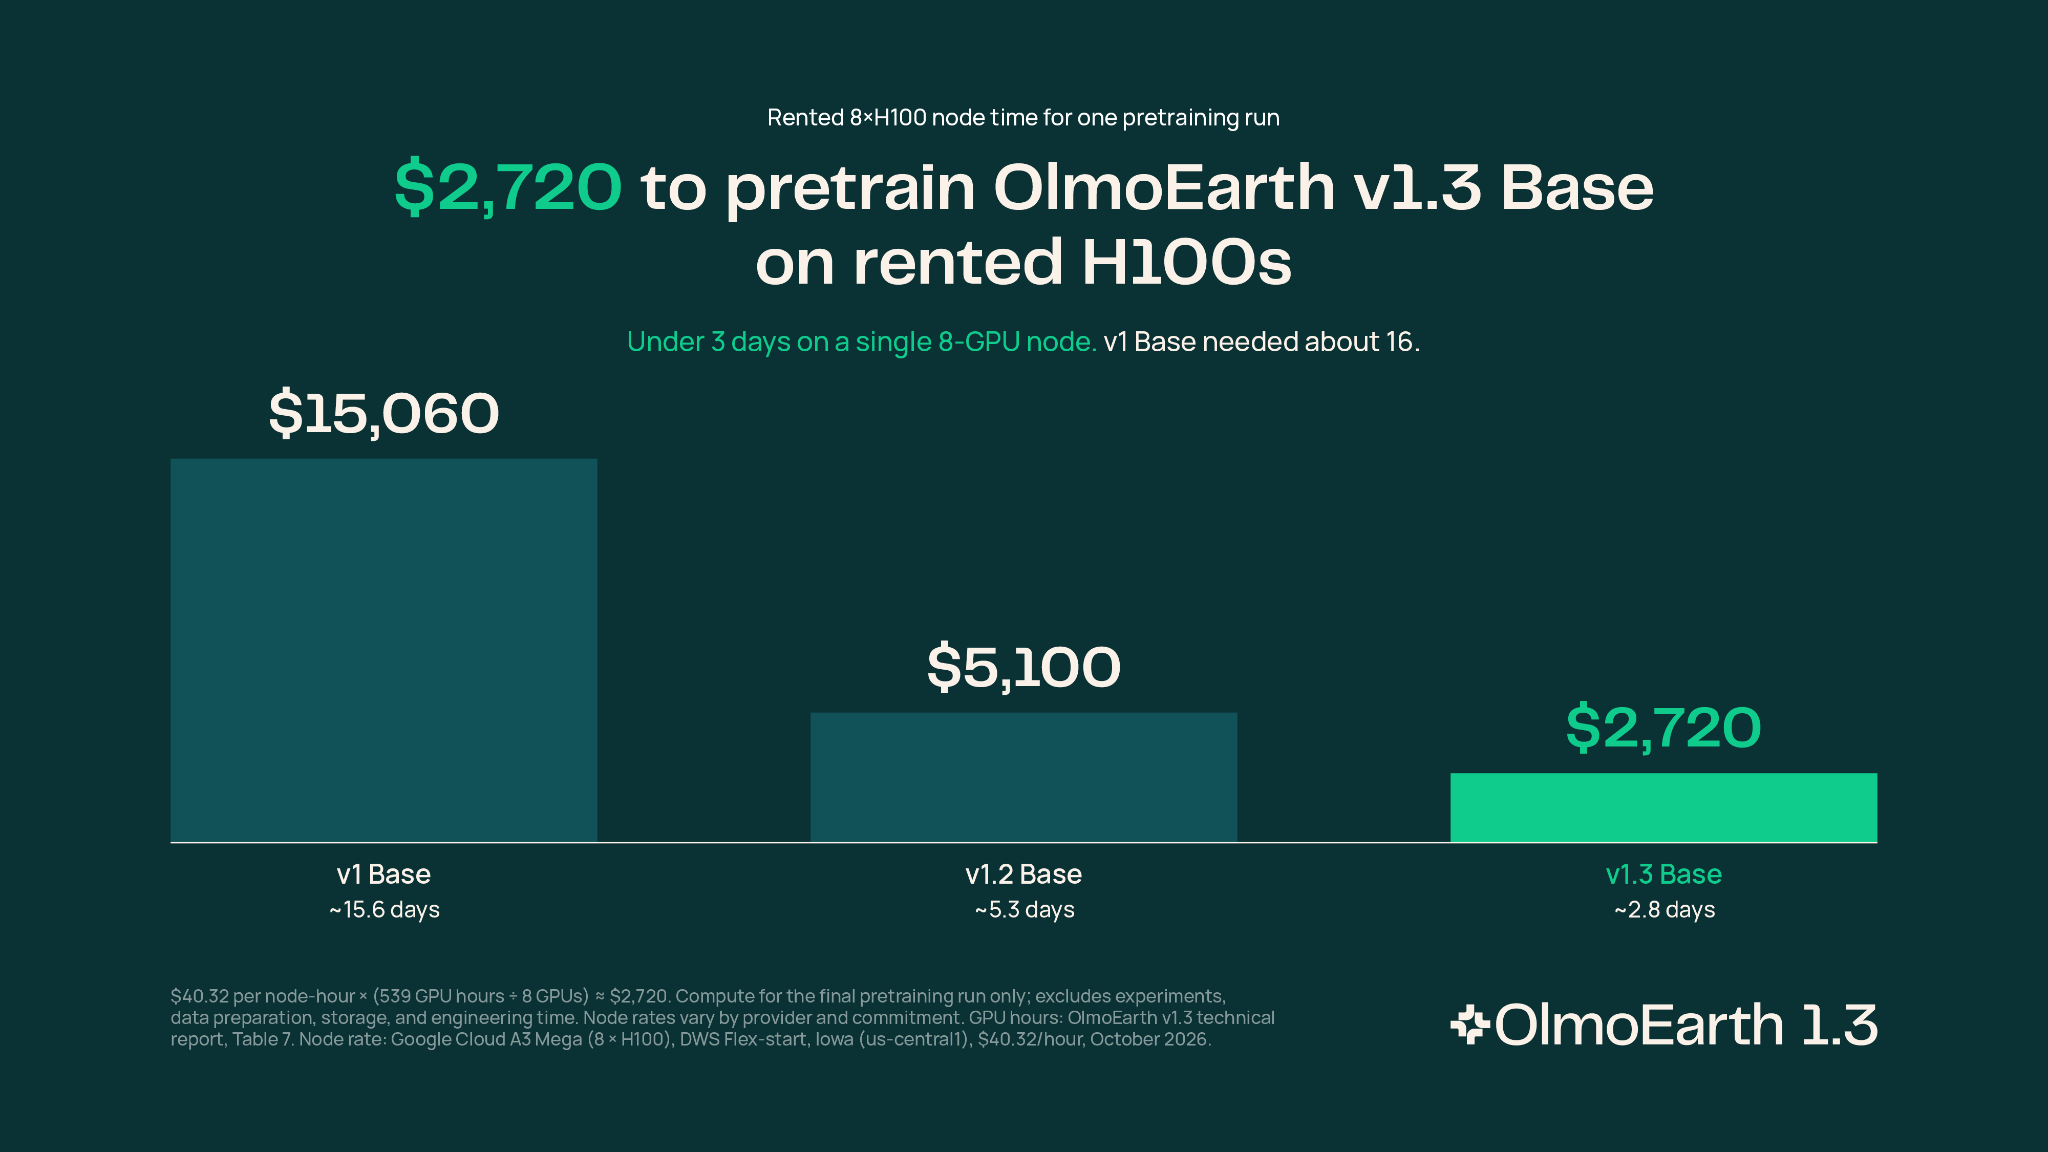
If you wanted to reproduce it, pre-training OlmoEarth v1.3 Base would cost roughly $2,720 of rented H100 time for the final run. The weights, data, and code are all open.
One place, nine years
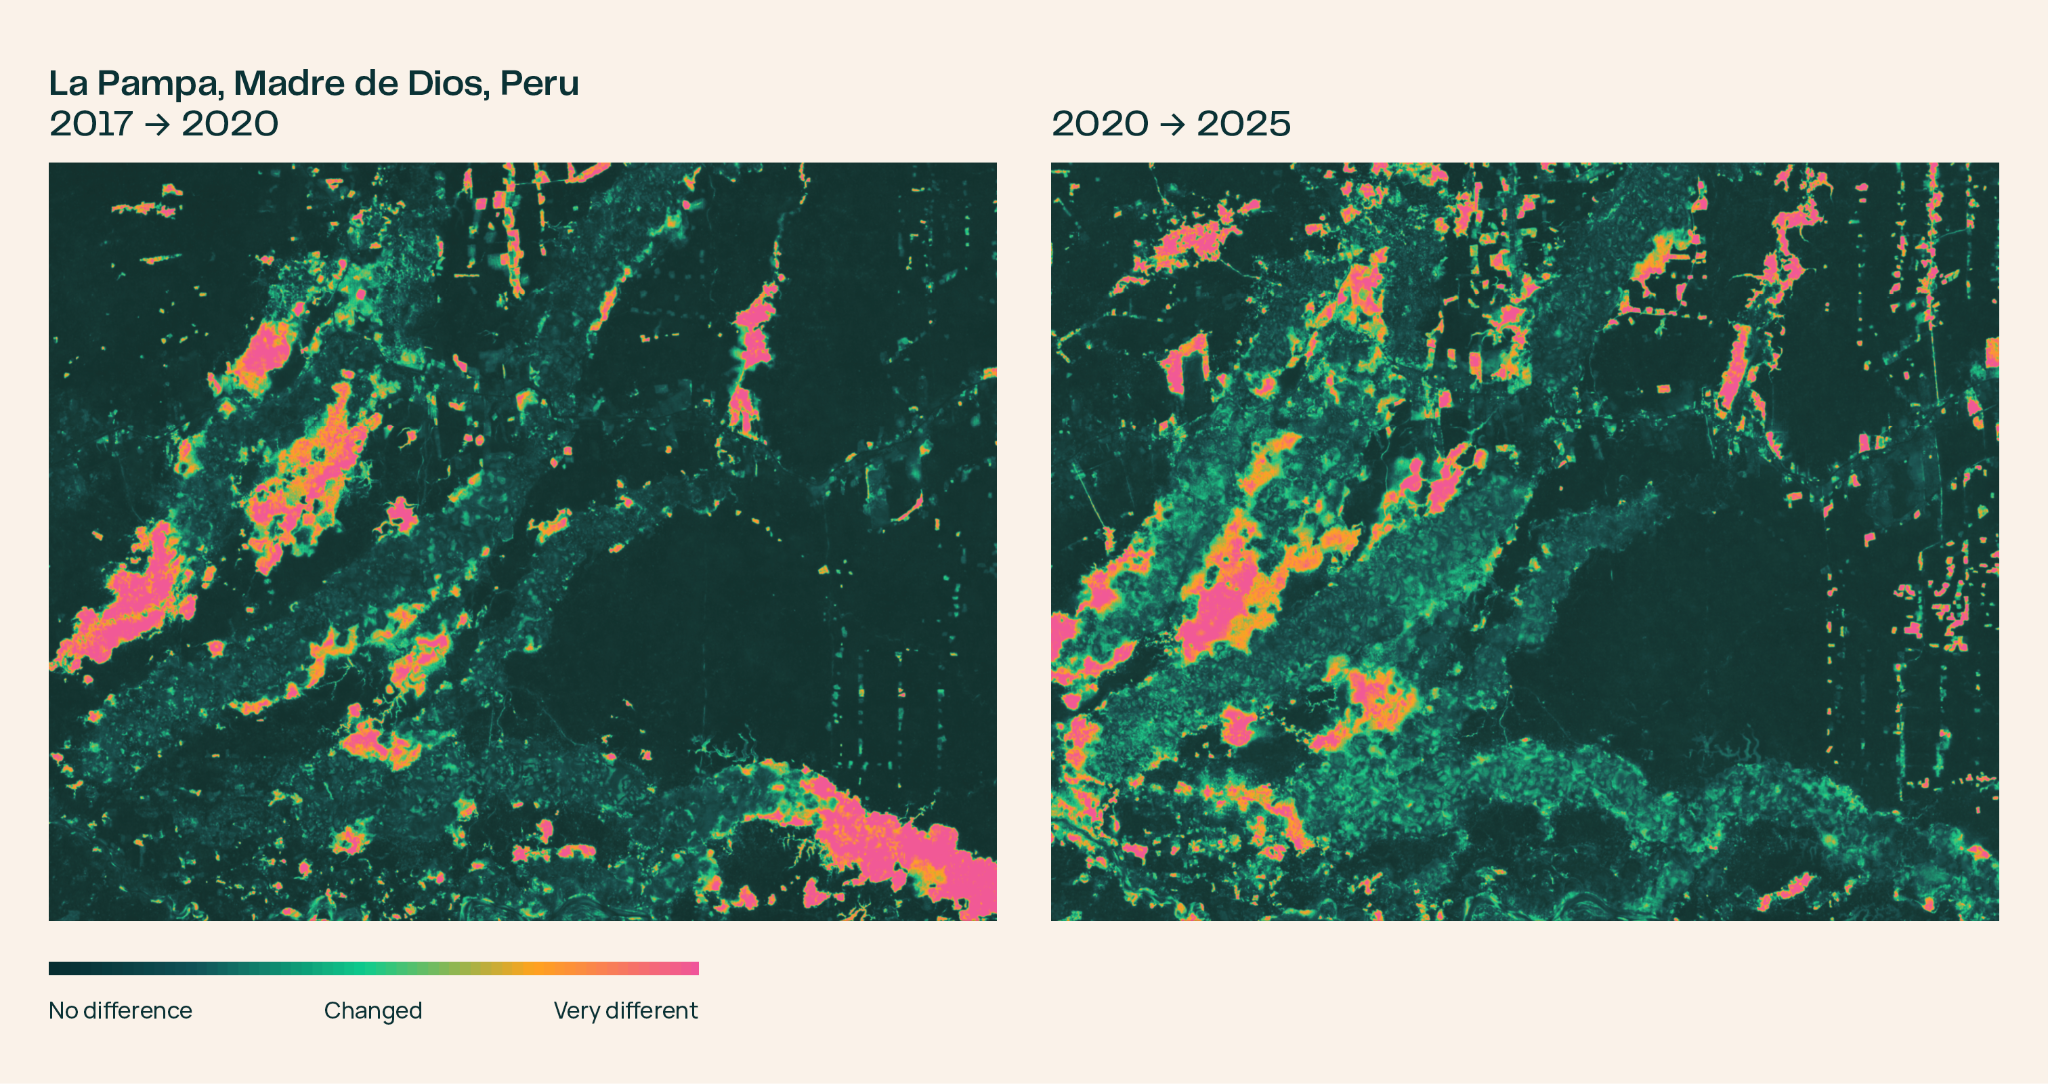
How much each pixel’s embedding changed between 2017 and 2020 (left) and 2020 and 2025 (right). Magenta is the largest change. Left: mining spreading southeast, the big patch at lower right. Right: that corner has gone quiet; the change now sits in the older mining zone to the west, part regrowth, part renewed digging. Explore it yourself in the OlmoEarth Embeddings Explorer.
In Peru's Madre de Dios region, illegal gold mining around La Pampa peaked in 2017 and 2018, clearing more than 1,200 hectares of forest in the buffer zone of the Tambopata National Reserve, according to Amazon Conservation's MAAP monitoring program. In February 2019, Peru's Operation Mercurio shut most of it down. The question ever since has been, did it stay down?
The embeddings help answer that. Compare each pixel's vector across years, no model training required, and the 2017 to 2020 pair lights up where the mining was spreading to the southeast. Run the same comparison from 2020 to 2025, and the signal shifts. The crackdown is visible in the embeddings.
The more interesting part is what the second map still shows. It is not dark. According to MAAP, pockets in the northwest kept operating, and the old mining zone keeps changing as the land recovers. The embeddings register that too. The reprieve was brief, and the pressure is building again. In August 2026, the Associated Press reported, Peru sent navy patrols back into the reserve after prosecutors found mining had crossed into Tambopata itself.
Our interactive story opens on this stretch of Madre de Dios, and walks through several other examples from there.

The OlmoEarth Embeddings Explorer
The OlmoEarth Embeddings Explorer is an interactive analysis tool built from the embeddings themselves, rendered as a false-color map of the planet. Pan anywhere, flip between years to see how landscapes have changed, and pull up the underlying Sentinel-2 imagery to check the map against the real thing. Then start asking questions: click a place to find others that look similar, or drop a few labeled points and train a small classifier on the spot, then export the result as a GeoTIFF. No account, no setup required.
For many teams, testing an idea against OlmoEarth has meant a fine-tuning run, on the order of hours. In the explorer, a first pass takes seconds. You can analyze entire regions from a handful of labels, no GPU needed. When a task calls for fine-tuning, the embeddings can help you decide whether it deserves the compute, and where the model falls short.
The archive behind the Explorer holds embeddings at 10-meter resolution, roughly 150 TB per year, covering land and adjacent coastal waters. At launch, 2025, 2024, and 2023 are global, and 2017 to 2022 cover select countries, with more coverage on the way. You can retrieve the embeddings in the full 128-dimensional version or the lighter 64-dimensional version. Every embedding also comes with a record of where it came from. For each 20-kilometer tile and year, open provenance tables list the Sentinel-1, Sentinel-2, and Landsat scenes the model read, with links to the public catalogs that host them, so you can trace any pixel back to the imagery behind it.
Get started
This release includes the OlmoEarth v1.3 Base model, the precomputed global embeddings, the OlmoEarth Embeddings Explorer, and the technical report. If your work needs a specific time window, OlmoEarth Studio runs the same model over the dates, modalities, and resolution that you choose, and a tutorial shows how to generate embeddings on your own compute. These tools work together: explore in the Embeddings Explorer, fine-tune in Studio when a task calls for it, and take your map from there. Everything is published under the OlmoEarth Artifact License, the same open license as v1 and v1.2.
Pull the embeddings for a place you care about, put your question to them, and show us what you find.
來源:Hugging Face Blog · huggingface.co